Skip to content
#machine learning #computer vision Preprint Open access

Scaling 3D Visual Grounding in Abdominal CT

Sam Church Danyal Maqbool Joshua D. Warner Andrew Voter Junjie Hu Meghan G. Lubner Tyler J. Bradshaw
Oct 2026
Machine Learning Computer Vision

Abstract

Visual grounding models can enhance radiology workflows by linking report findings to image regions. This is particularly valuable for 3D CT, where findings often occupy a tiny fraction of the volume. Training 3D grounding models requires large sets of paired phrases and regions, and building such datasets is expensive, requiring radiologists to annotate images by hand. We posit that this supervision is already created implicitly during routine reporting, as radiologists frequently place 2D annotations (e.g., distance measurement, arrows) on key images to make measurements and to support report interpretation. We introduce an automated pipeline that converts these routine clinical annotations into large-scale phrase-region supervision for 3D visual grounding. The pipeline links each annotation to the corresponding finding in the report through metadata matching, then uses a promptable 3D segmentation model to convert the 2D annotation into a volumetric mask. This produces phrase-mask-volume datasets without requiring additional radiologist annotation. Applied to a single institution's clinical picture archiving and communication system (PACS), our approach generated 105K phrase-mask-volume triplets from 59K abdominal CT exams. We also introduce two abdominal CT grounding benchmarks, LocusBench-Onc and LocusBench-ED, which comprise 240 oncology and 260 emergency-department radiologist-reviewed phrase-mask-volume triplets, respectively, with the latter spanning 13 distinct categories such as appendicitis, hematoma, and hernia. We further introduce LocusCT, a 3D visual grounding model trained on this dataset, which achieves hit rates of 0.725 on LocusBench-Onc and 0.773 on LocusBench-ED, substantially outperforming comparator models. These results show that routine PACS annotations are a scalable, previously unused source of supervision for 3D visual grounding.

View source

Similar papers

#computer vision Review Sep 2017

Agile Software Development Methods: Review and Analysis

This publication proposes a definition and a classification of agile software development approaches and analyses ten software development methods that can be characterized as being "agile" against the defined criterion.

P. Abrahamsson, O. Salo, Jussi Ronkainen et al. · 727 citations · ⚡54
#computer vision Jun 2008

The impact of agile practices on communication in software development

The study shows that agile practices improve both informal and formal communication, but indicates that, in larger development situations involving multiple external stakeholders, a mismatch of adequate communication mechanisms can sometimes even hinder the communication.

M. Pikkarainen, Jukka Haikara, O. Salo et al. · 401 citations · ⚡48
#machine learning Review Open access Oct 2014

Software development in startup companies: A systematic mapping study

The results indicate that software engineering work practices are chosen opportunistically, adapted and configured to provide value under the constrains imposed by the startup context.

Nicolò Paternoster, Carmine Giardino, M. Unterkalmsteiner et al. · 394 citations · ⚡54

Diffusion models as plug-and-play priors

The possibility of inferring high-dimensional data inference in a model that consists of a prior and an auxiliary differentiable constraint given some additional information is considered, thereby allowing a range of potential applications in adapting models to new domains and tasks.

Alexandros Graikos, Esmeralda S. Whitammer, N. Jojic et al. · 316 citations · ⚡15

Trajectory Balance: Improved Credit Assignment in GFlowNets

It is proved that any global minimizer of the trajectory balance objective can define a policy that samples exactly from the target distribution, and empirically demonstrate the benefits of the trajectories balance objective for GFlowNet convergence, diversity of generated samples, and robustness to long action sequenc...

Esmeralda S. Whitammer, Moksh Jain, Emmanuel Bengio et al. · 302 citations · ⚡60

Related blog posts

Microsoft Research Blog Aug 11, 2026

Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement

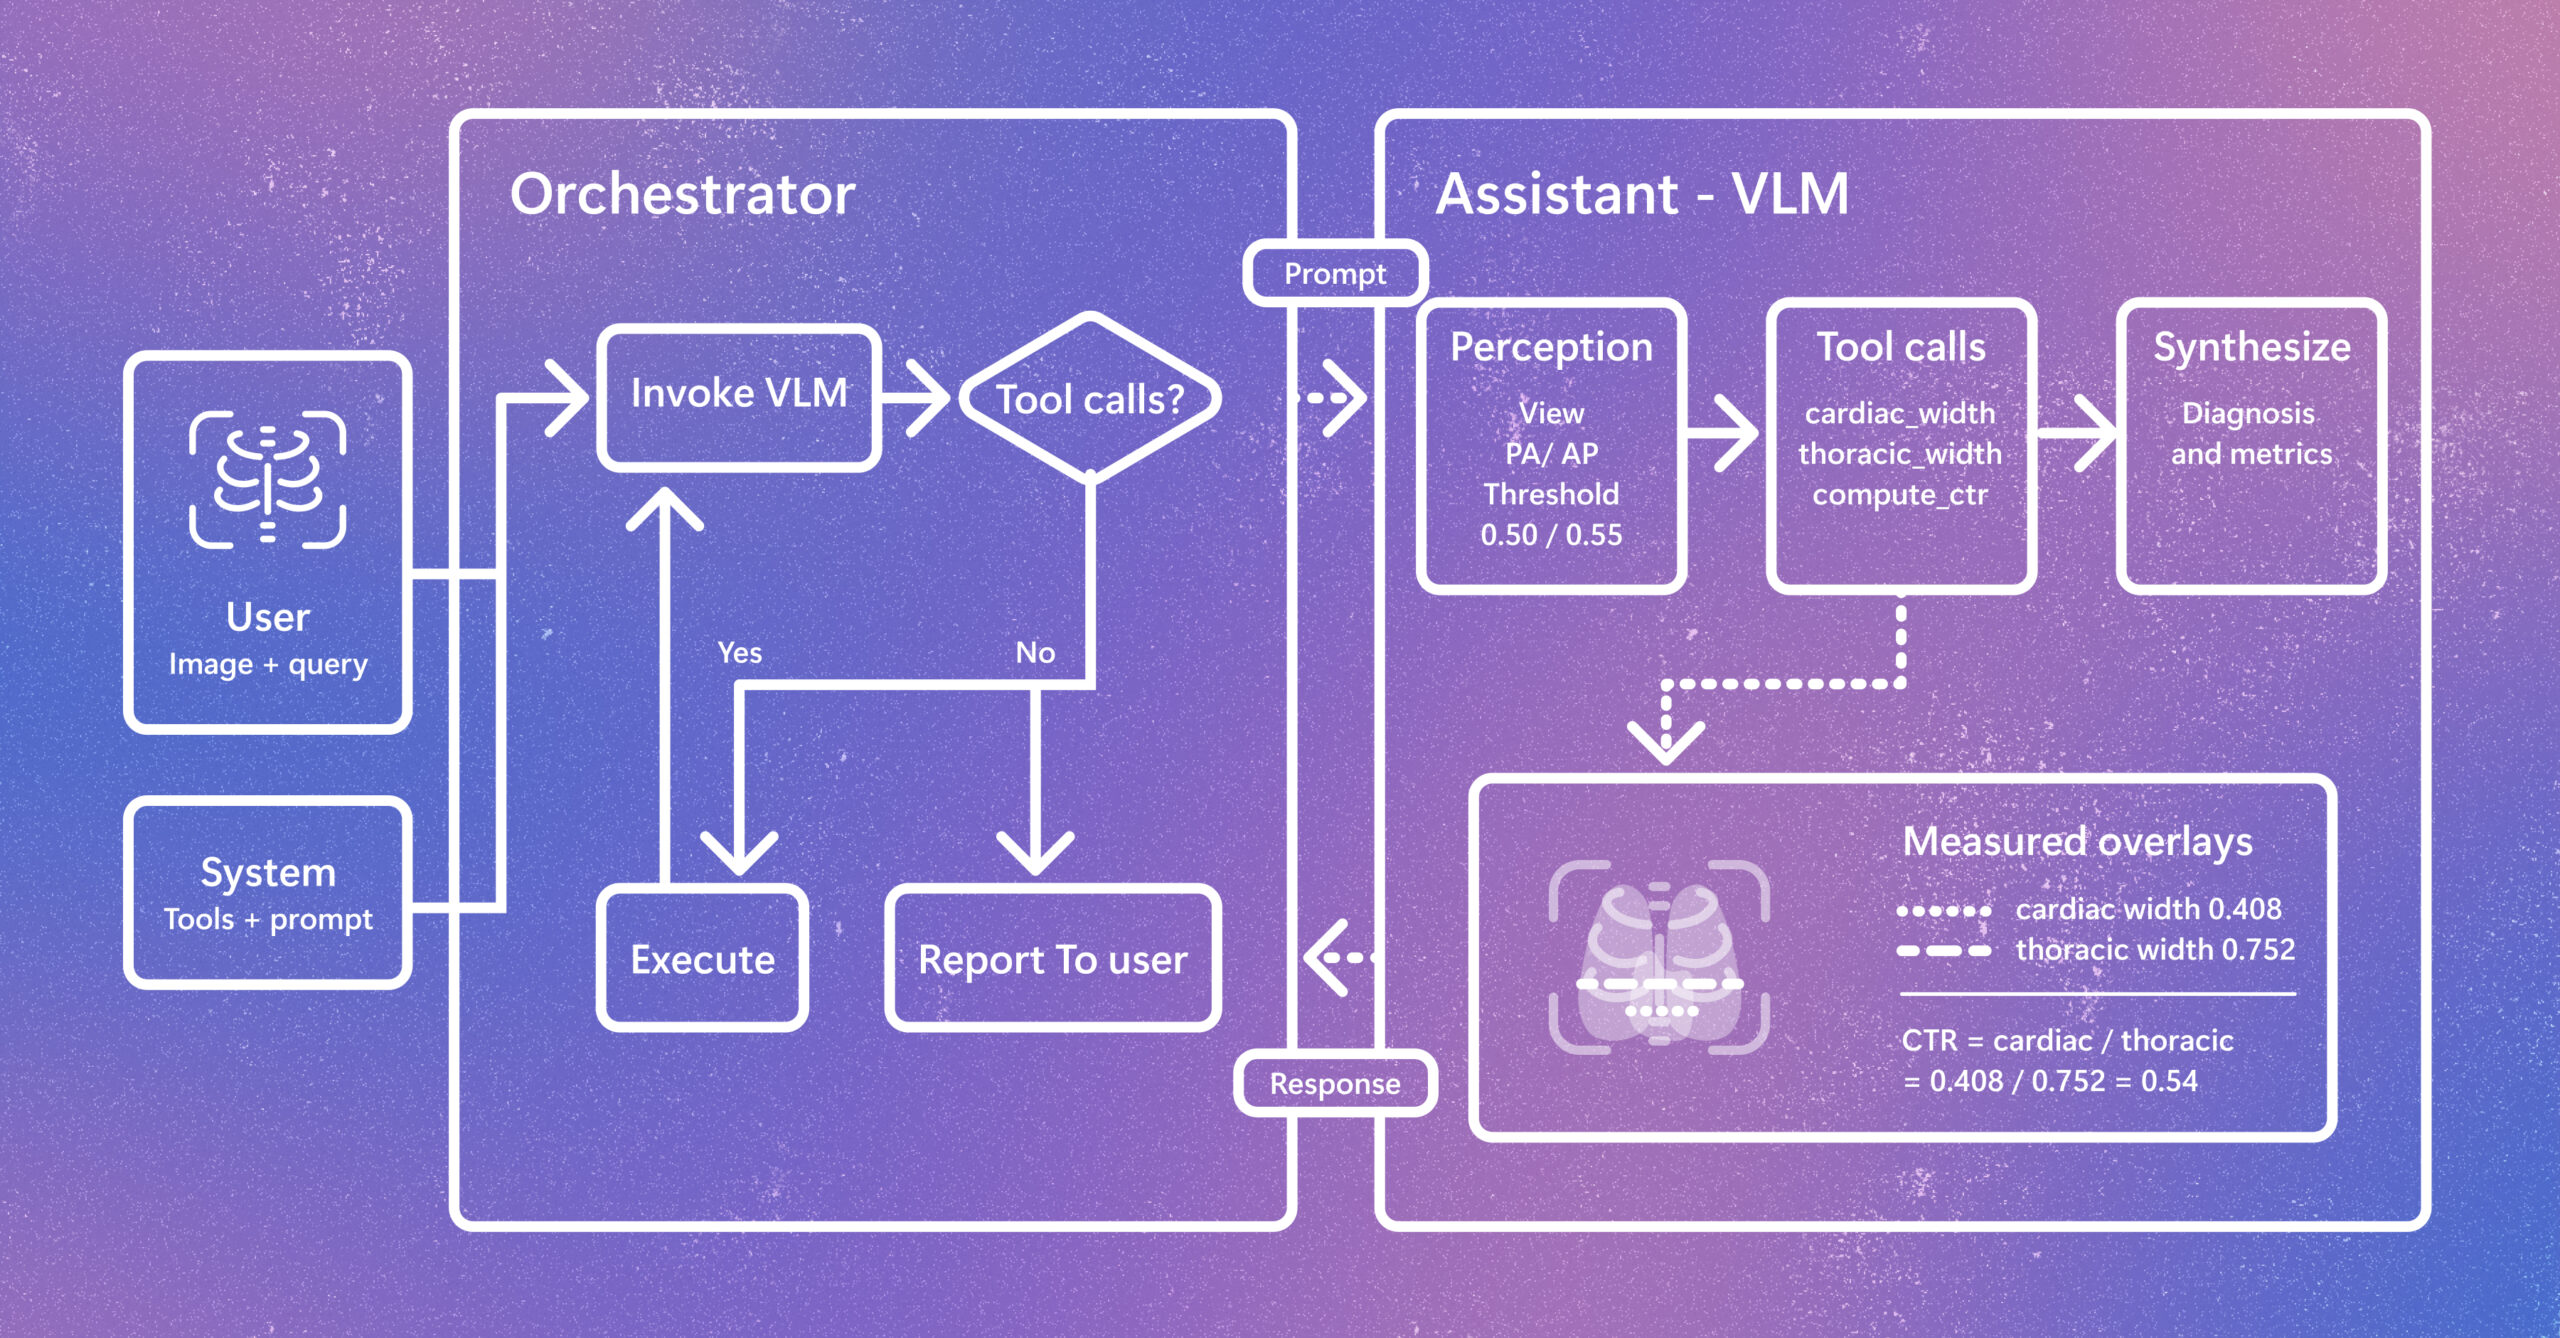
Radiology AI is evolving beyond report generation. CARE-X explores a unified approach that combines flexible reasoning, calibrated predictions, and measurement-based tools for chest X-ray interpretation. The post Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement appeared first on Microsoft Research.

MIT News · Artificial Intelligence Oct 7, 2026

Discovering the value of humanistic inquiry

Students in MIT’s Concourse program delve deeply into the human condition, debate challenging questions, and learn to develop judgment about issues that can’t be quantified.

We use cookies to run the site and, with your consent, for analytics and to show ads. See our Cookie Policy.
