Prior audio-visual self-supervised learning methods rely on mechanisms such as EMA target encoders, prediction heads, reconstruction decoders, and contrastive losses. We introduce LeAVJEPA, the first audio-visual encoder trained under LeJEPA's collapse-free objective. A single early-fusion Vision Transformer processes audio, video, and joint audio-video inputs. Modality dropout treats a missing modality as another view of the same event, making cross-modal alignment implicit in the objective. The model aligns global embeddings with modality-specific local embeddings, and SIGReg prevents representational collapse. A controlled ablation identifies modality dropout as the key mechanism for audio-visual alignment. Despite the architectural simplicity, LeAVJEPA reaches 36.0 mAP on AudioSet-20K and 91.3% accuracy on ESC-50 under frozen evaluation. After fine-tuning, it reaches 61.1% accuracy on VGGSound, and its embeddings support zero-shot audio-visual retrieval.
This publication proposes a definition and a classification of agile software development approaches and analyses ten software development methods that can be characterized as being "agile" against the defined criterion.
P. Abrahamsson, O. Salo, Jussi Ronkainen et al.· arXiv.org· 727 citations· ⚡54
The study shows that agile practices improve both informal and formal communication, but indicates that, in larger development situations involving multiple external stakeholders, a mismatch of adequate communication mechanisms can sometimes even hinder the communication.
M. Pikkarainen, Jukka Haikara, O. Salo et al.· Empirical Software Engineeri...· 401 citations· ⚡48
The results indicate that software engineering work practices are chosen opportunistically, adapted and configured to provide value under the constrains imposed by the startup context.
Nicolò Paternoster, Carmine Giardino, M. Unterkalmsteiner et al.· Information and Software Tec...· 394 citations· ⚡54
The possibility of inferring high-dimensional data inference in a model that consists of a prior and an auxiliary differentiable constraint given some additional information is considered, thereby allowing a range of potential applications in adapting models to new domains and tasks.
Alexandros Graikos, Esmeralda S. Whitammer, N. Jojic et al.· Neural Information Processin...· 316 citations· ⚡15
Exploring how generative AI could make machine vision more accessible to businesses. The post GenEye in a Box: Making Machine Vision Something You Can Just Ask For appeared first on GPT-Lab.
Microsoft Research Blog· microsoft.comAug 11, 2026
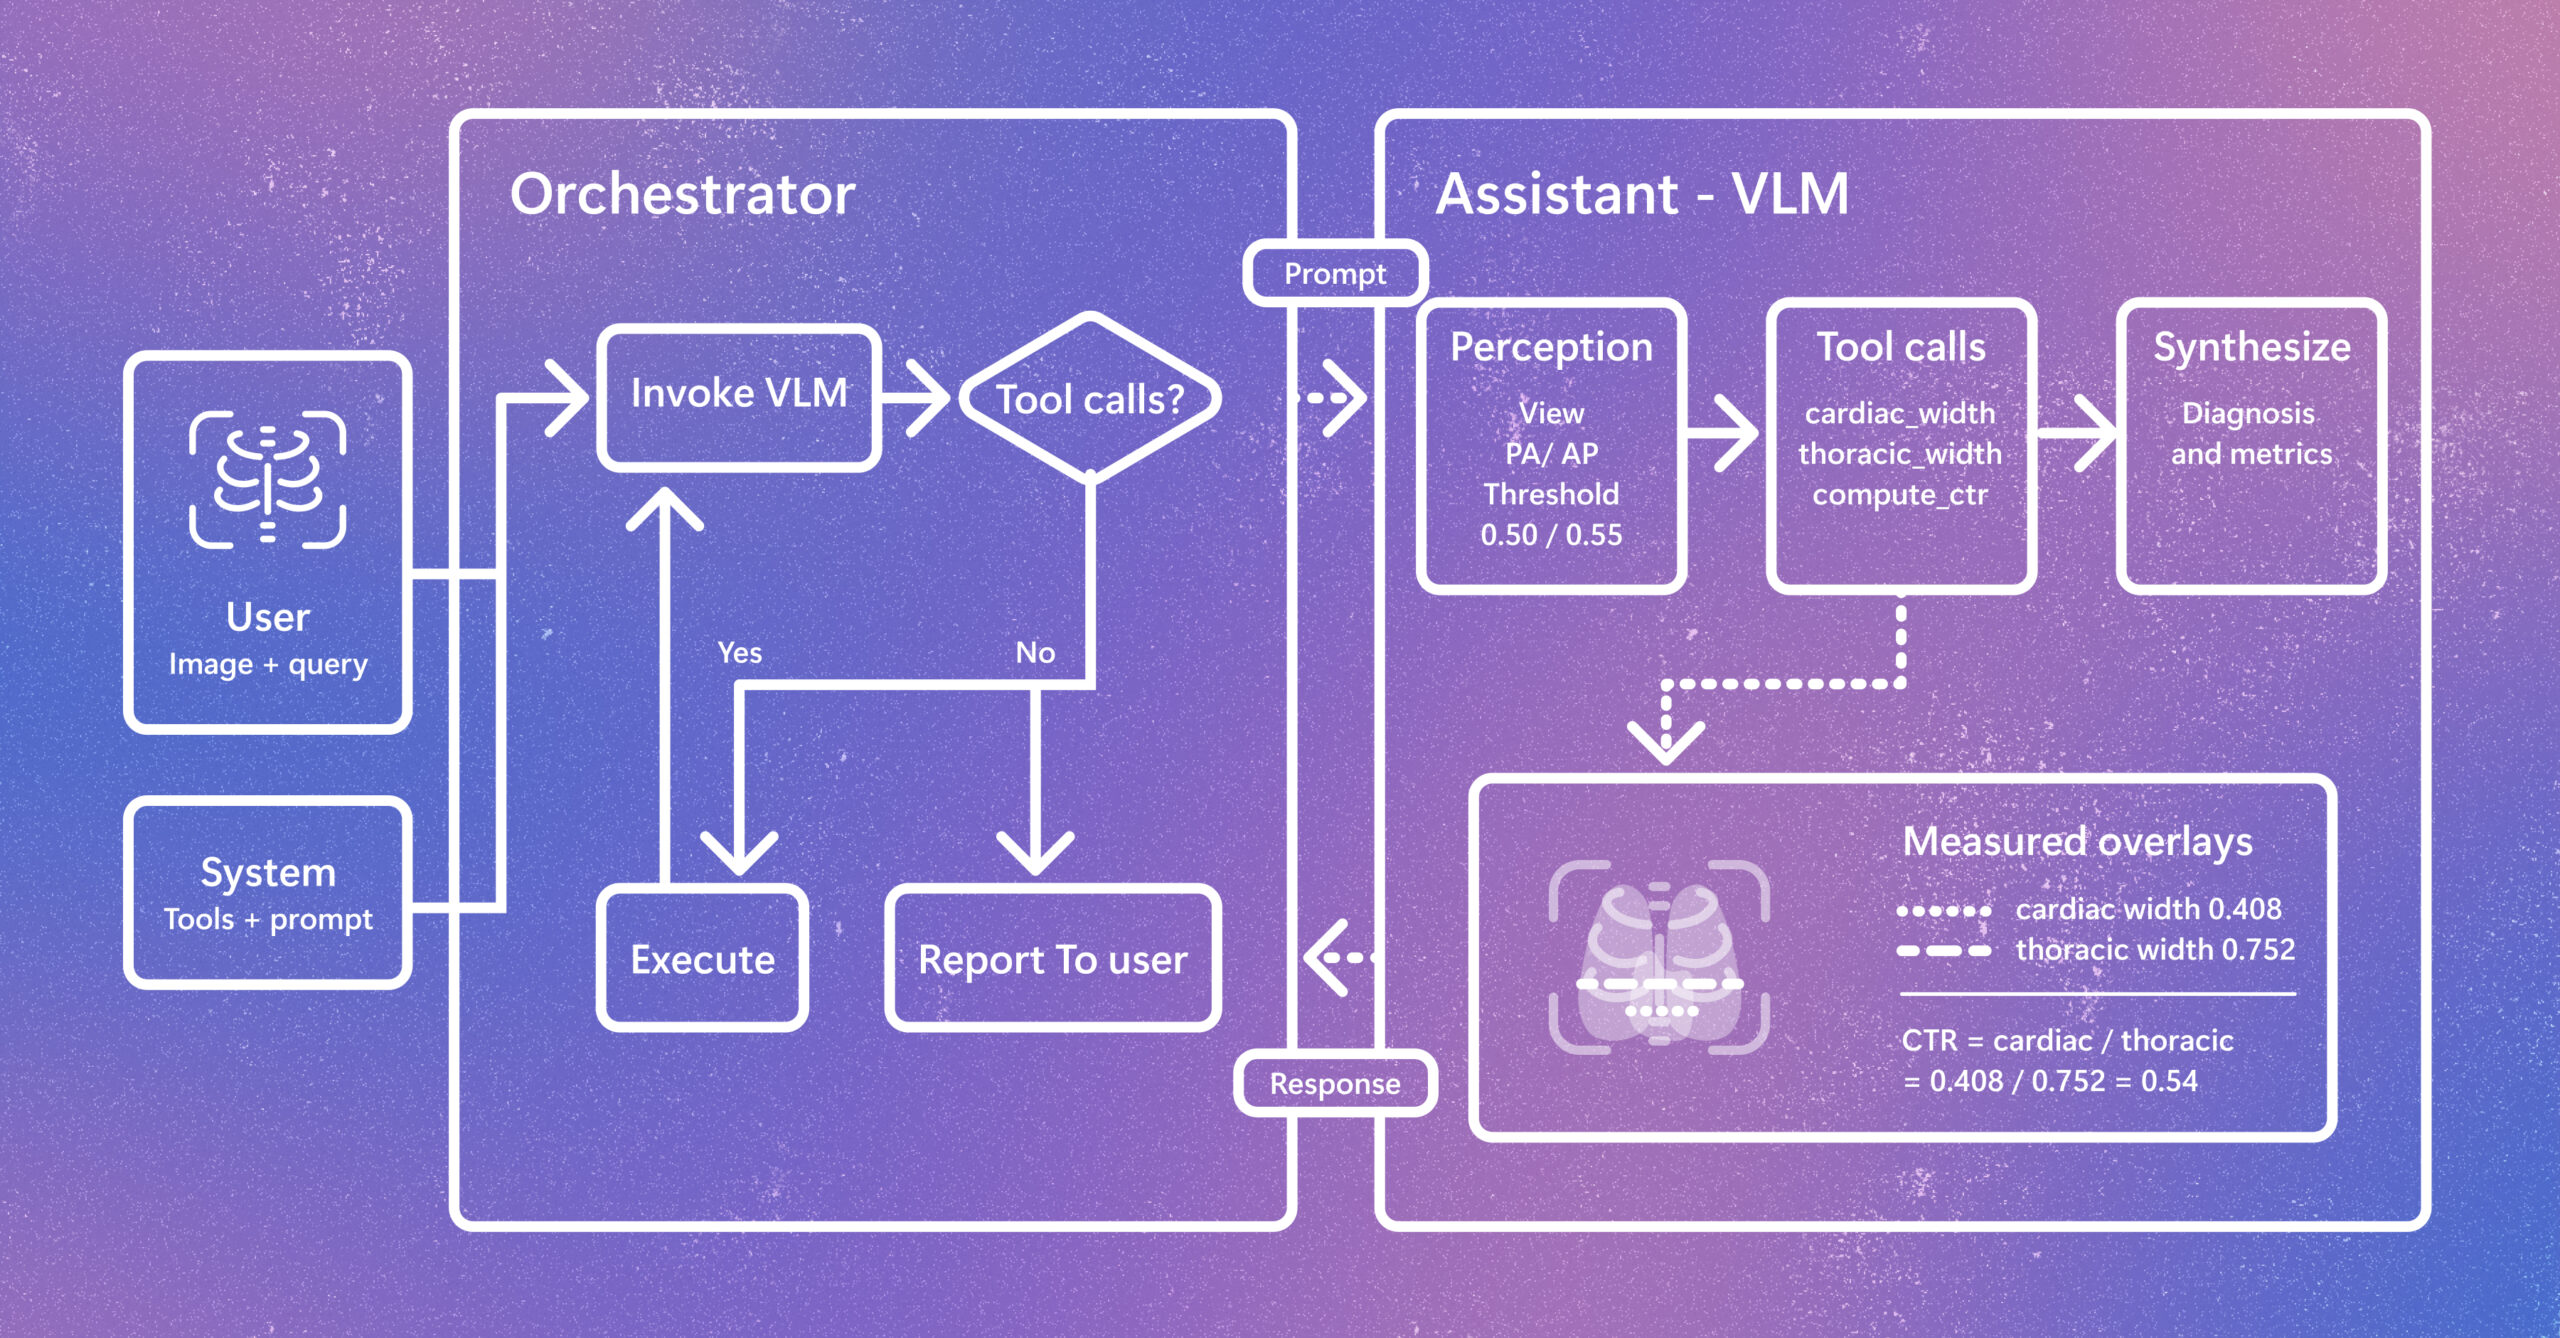
Radiology AI is evolving beyond report generation. CARE-X explores a unified approach that combines flexible reasoning, calibrated predictions, and measurement-based tools for chest X-ray interpretation. The post Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement appeared first on Microsoft Research.
Students in MIT’s Concourse program delve deeply into the human condition, debate challenging questions, and learn to develop judgment about issues that can’t be quantified.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.