The choice of post-training data for large language models substantially affects downstream performance. Gradient-based data selection is a popular approach that ranks training data by how well their gradients align with those of a small validation set. However, ranking with full-parameter gradients requires an expensive backward pass on every sample, making computation intractable for large candidate pools. This raises a natural question: can we approximate full-gradient features at a fraction of the cost? Conveniently, we find that output-layer gradients suffice for effective data selection, yet require only the cheaper forward pass. We implement this as LESSER, a drop-in wrapper for selection methods that reduces the feature-extraction FLOP cost by $9.7\times$ for SFT and $3.0\times$ for RL benchmarks, while tracking full-gradient performance on downstream tasks. Empirically, we find that even when output-layer and full gradients rank individual samples differently, they select batches with aligned gradients.
Supporting data, adapters, predictions and code for the article *Low-Cost LoRA Fine-Tuning of Small Language Models for Multi-Step Arithmetic Reasoning* by Jake O'Grady, Asena Isik Gürhan, Chee Fong Ting and Effirul Ramlan (University of Galway). We generated 20,000 GSM8K-derived arithmetic problems with step-by-step s...
O'Grady, Jake, Gürhan, Asena Isik, Chee, Fong Ting et al.· Zenodo (CERN European Organi...· 465 citations
The results indicate that software engineering work practices are chosen opportunistically, adapted and configured to provide value under the constrains imposed by the startup context.
Nicolò Paternoster, Carmine Giardino, M. Unterkalmsteiner et al.· Information and Software Tec...· 394 citations· ⚡54
The possibility of inferring high-dimensional data inference in a model that consists of a prior and an auxiliary differentiable constraint given some additional information is considered, thereby allowing a range of potential applications in adapting models to new domains and tasks.
Alexandros Graikos, Esmeralda S. Whitammer, N. Jojic et al.· Neural Information Processin...· 316 citations· ⚡15
It is proved that any global minimizer of the trajectory balance objective can define a policy that samples exactly from the target distribution, and empirically demonstrate the benefits of the trajectories balance objective for GFlowNet convergence, diversity of generated samples, and robustness to long action sequenc...
Esmeralda S. Whitammer, Moksh Jain, Emmanuel Bengio et al.· Neural Information Processin...· 302 citations· ⚡60
The results are packaged in the Greenfield Startup Model (GSM), which explains the priority of startups to release the product as quickly as possible, and the need to shorten time-to-market, by speeding up the development through low-precision engineering activities.
Carmine Giardino, Nicolò Paternoster, M. Unterkalmsteiner et al.· IEEE Transactions on Softwar...· 178 citations· ⚡14
This state-of-practice investigation was performed using a literature review followed by a multiple-case study approach and presents how inconsistency between managerial strategies and execution can lead to failure by means of a behavioral framework.
Carmine Giardino, Xiaofeng Wang, P. Abrahamsson· International Conference on...· 175 citations· ⚡19
Adaptive AI agents can help make BIM data more machine-readable by navigating IFC models, interpreting inconsistent information, and mapping it to defined standards. In this blog, Alok Rawat shares findings from a real-world pilot in construction workflows. The post Adaptive AI Agents in Construction Workflows appeared first on GPT-Lab.
What does it take to trust AI-driven HVAC optimization? Our AI Model Factory combines agents, machine learning, reinforcement learning and deterministic checks in a governed workflow designed for messy, real-world building data. The post We built an AI factory for HVAC control appeared first on GPT-Lab.
MIT News · Artificial Intelligence· news.mit.eduAug 18, 2026
A new method for surgically removing training examples from a model reveals that as datasets grow, the link between what a model learns and what it produces dissolves.
Microsoft Research Blog· microsoft.comJul 30, 2026
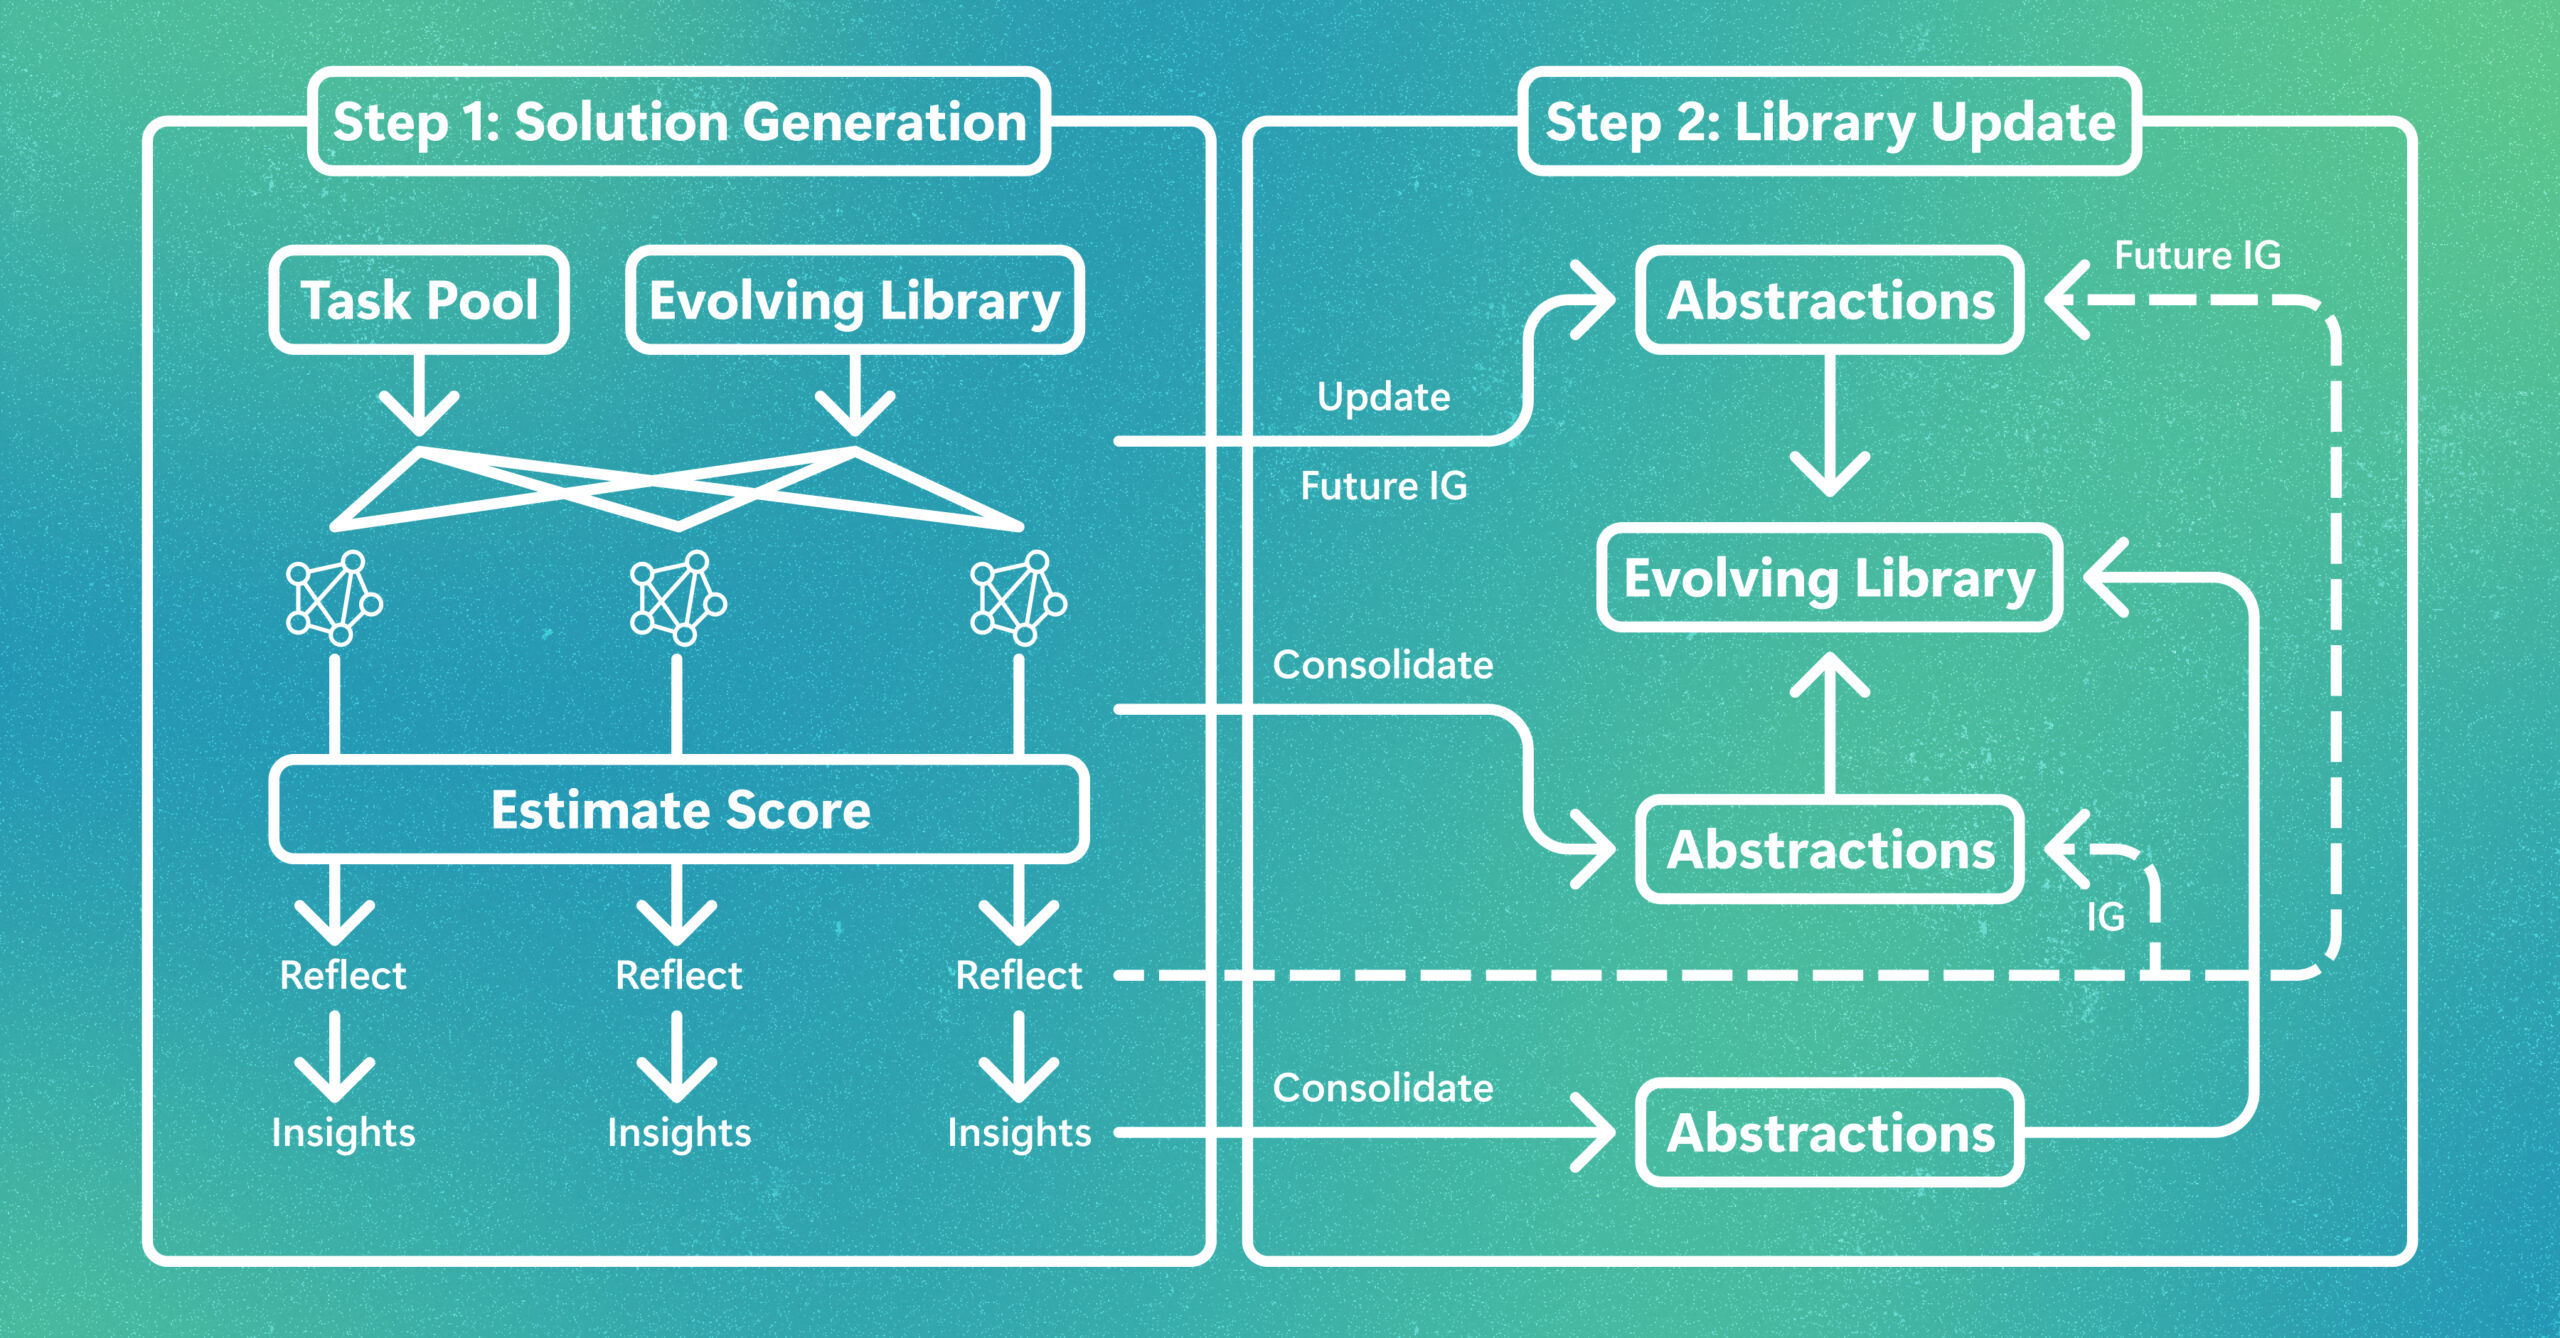
LLMs do not get smarter just by remembering more. EvoLib turns experience into evolving knowledge, taking reusable skills and insights that help models learn and adapt across tasks long after deployment. The post EvoLib: Turning experience into evolving knowledge appeared first on Microsoft Research.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.