Results show that recurrent token mixing can provide an efficient alternative to global softmax attention for high-resolution dense prediction and edge deployment, and are shown to be faster than FLA v0.5.
Abstract
Self-attention-based vision backbones perform well on dense prediction, but the quadratic computational cost of global softmax attention limits their efficiency as image resolution increases. We introduce Gated Token Recurrence (GTR), a softmax-free recurrent vision backbone that combines gated linear attention, alternating spatial scan directions, and spatially enhanced SwiGLU blocks. GTR is distilled from a detection-specialized DINOv3 teacher using only final-layer patch-token alignment through a linear projection and squared $\ell_2$ loss, without masked-token prediction or intermediate-layer supervision. With Objects365 detector pre-training, GTR-L achieves 58.9 box AP on COCO \texttt{val2017} with 1.908\,ms median batch-one latency under compiled FP16 execution on an RTX~4090. The same backbone also transfers to instance segmentation, pose estimation, oriented detection, semantic segmentation, and monocular depth estimation. In an isolated kernel benchmark, our specialized chunkwise CUDA operator is $4.0\times$ faster than FLA v0.5.0 at 1.6K tokens on RTX~4090. TensorRT deployment on DRIVE AGX Thor achieves 2.282--8.769\,ms median batch-one latency across the evaluated models. These results show that recurrent token mixing can provide an efficient alternative to global softmax attention for high-resolution dense prediction and edge deployment. Project page: https://intellindust-ai-lab.github.io/projects/GTR/
GramLoop is introduced, a training-free framework that replays a short transformer window and controls each replay through final-layer cosine-Gram consistency, which improves object detection and semantic segmentation under corruptions, perturbations, and natural shifts.
Yang Chen, Can-Yu Shen, Xin-Zhe Rao et al.· 0 citations
This paper revisits long-used fundamental operators and proposes three operator-level redesigns: Subtractive Residual Connection, Learnable Gating Response Function (LGRF), and statistics-discrepancy-guided Dynamic Dual Normalization (DDN).
To adapt billion-parameter Vision Transformers for long-video understanding, recent methods freeze the backbone and train lightweight convolutional modules. While effective for parameter-efficient training, existing adapters do not reduce inference-time computation, leaving scalability with respect to video length larg...
Ricardo Pizarro, Roberto Valle, J. M. Buenaposada et al.· 0 citations
A detection-guided dynamic attention steering system that leverages the locality insight from CNNs to efficiently steer a VLM’s attention toward more relevant sections of an image and demonstrates the effectiveness of combining different model architectures to harness their respective strengths for advancing VLM capabi...
Alan William Zhang, Rui Pan, Mike Wong et al.· 0 citations
While Mamba-based models have shown strong potential for long sequence modeling, adapting them to vision is challenging due to the requirement of local neighborhood correlations and multi-directional spatial contexts for visual understanding. In this paper, we present LiAuto-MindViT, a novel hybrid vision backbone that...
Frequency-Decoupled Cross-Attention Knowledge Distillation (FD-CanKD) is presented as a detector-oriented framework that transfers teacher knowledge at three complementary levels: head-level prediction supervision, relation-level non-local context transfer, and frequency-level component-selective alignment.
Exploring how generative AI could make machine vision more accessible to businesses. The post GenEye in a Box: Making Machine Vision Something You Can Just Ask For appeared first on GPT-Lab.
Microsoft Research Blog· microsoft.comAug 11, 2026
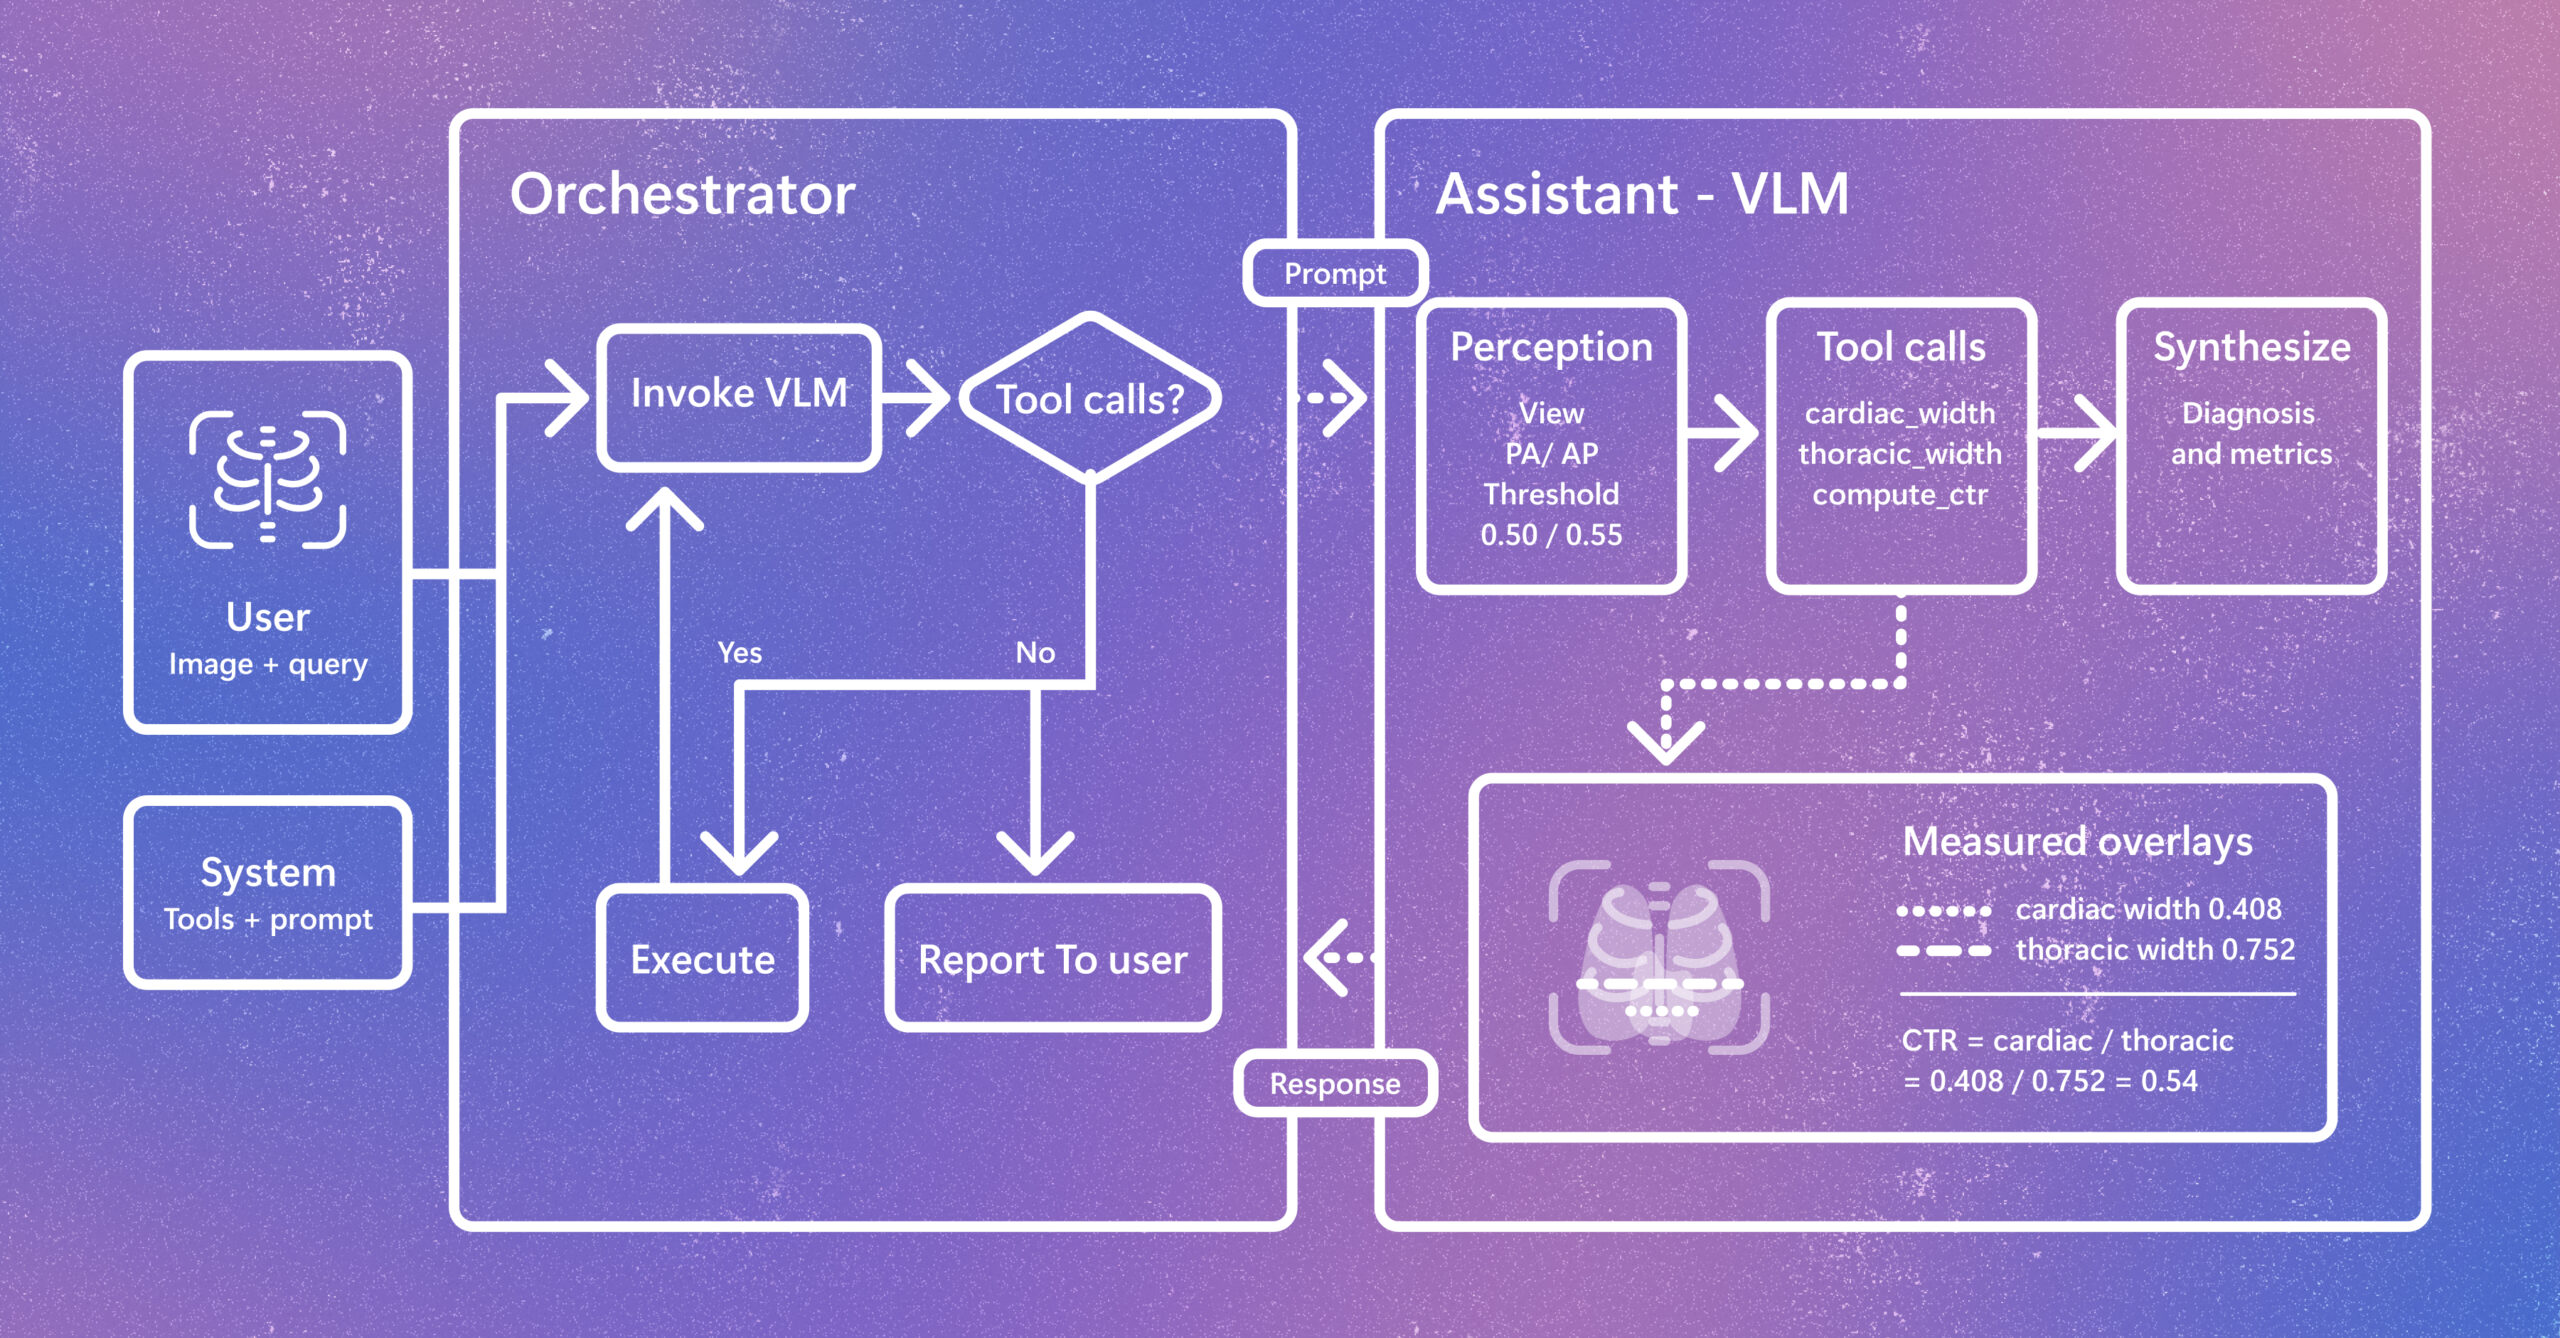
Radiology AI is evolving beyond report generation. CARE-X explores a unified approach that combines flexible reasoning, calibrated predictions, and measurement-based tools for chest X-ray interpretation. The post Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement appeared first on Microsoft Research.
StudentSim is a research system for evaluating and improving AI tutoring tools before they are tested with learners. It models how individuals may engage with tutors, giving feedback to improve tutor performance across subjects like chess, writing, and mathematics. The post Simulating student learning for better AI tutoring appeared first on Microsoft Research.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.