ReToken is a single learnable embedding trained as an explicit retrieval target that selects a sparse set of query-relevant visual tokens from a pre-filled visual KV cache that yields consistent gains across image and video benchmarks.
Abstract
Long visual context poses a challenge for vision-language models: performance degrades as the number of distractors grows, and processing all tokens at once is computationally infeasible under GPU memory constraints. We present ReToken, a single learnable embedding trained as an explicit retrieval target that selects a sparse set of query-relevant visual tokens from a pre-filled visual KV cache. Trained on only a small image-QA dataset, ReToken yields consistent gains across image and video benchmarks: on Visual Haystacks it improves Qwen3VL-8B by 13.4 points and InternVL3.5 by 12.4 points (>20% relative), and on LVBench it transfers zero-shot to long video for an 8.0-point gain with Qwen3VL-8B. Thanks to its lightweight design, both training and long-video inference fit on a single H100. Code is available at: https://github.com/avaxiao/ReToken
A training-free, Adaptive Visual Token Pruning (AVTP) framework, applicable to diverse LVLM architectures is proposed, and adaptive pruning ratios in multi-image contexts where images of higher importance retain proportionally more tokens are implemented.
Rongyang Zhang, Cheng-Qiang Lu, Cong Li et al.· 0 citations
It is shown that paragraph supervision enables effective use of long token sequences, whereas caption-only training degrades beyond 60 tokens, and paragraph supervision consistently benefits long-description benchmarks and hard negatives prove detrimental in text-only fine-tuning.
Mahyar Ghazanfari, Amin Tabrizian, Arsyi Aziz et al.· 0 citations
This work introduces \method, a Multi-scale Adaptive Vision Encoder, a Multi-scale Adaptive Vision Encoder that uses position-dependent gates to fuse shallow, intermediate, and deep features from a vision Transformer, preserving global semantics while enhancing edges, text, and local structure.
SaMer is proposed, an object-aware token merging framework that compresses image-side post-projector tokens into representative centroids while preserving the original late-interaction interface, and outperforms compression baselines and shows stronger phrase-level grounding, suggesting that efficient multi-vector retr...
Suhyeong Park, Junha Jung, Jungwoo Park et al.· arXiv.org· 1 citation
DIVE (Dynamic Iterative Visual Evidence Construction), a training-free framework that recasts visual-token pruning as dynamic evidence construction and builds a retained set of complementary, prompt-relevant evidence.
Cheng Zhong, Xiao An, Zijie Wang et al.· 0 citations
SEER is presented, a framework that learns to select query-relevant images through visual scanning and retrieve textual content only where needed, combining the efficiency of visual compression with the precision of text-based reasoning.
Jiawei Xu, Zhilin Zhai, Jinrui Fang et al.· 3 citations
Exploring how generative AI could make machine vision more accessible to businesses. The post GenEye in a Box: Making Machine Vision Something You Can Just Ask For appeared first on GPT-Lab.
Microsoft Research Blog· microsoft.comAug 11, 2026
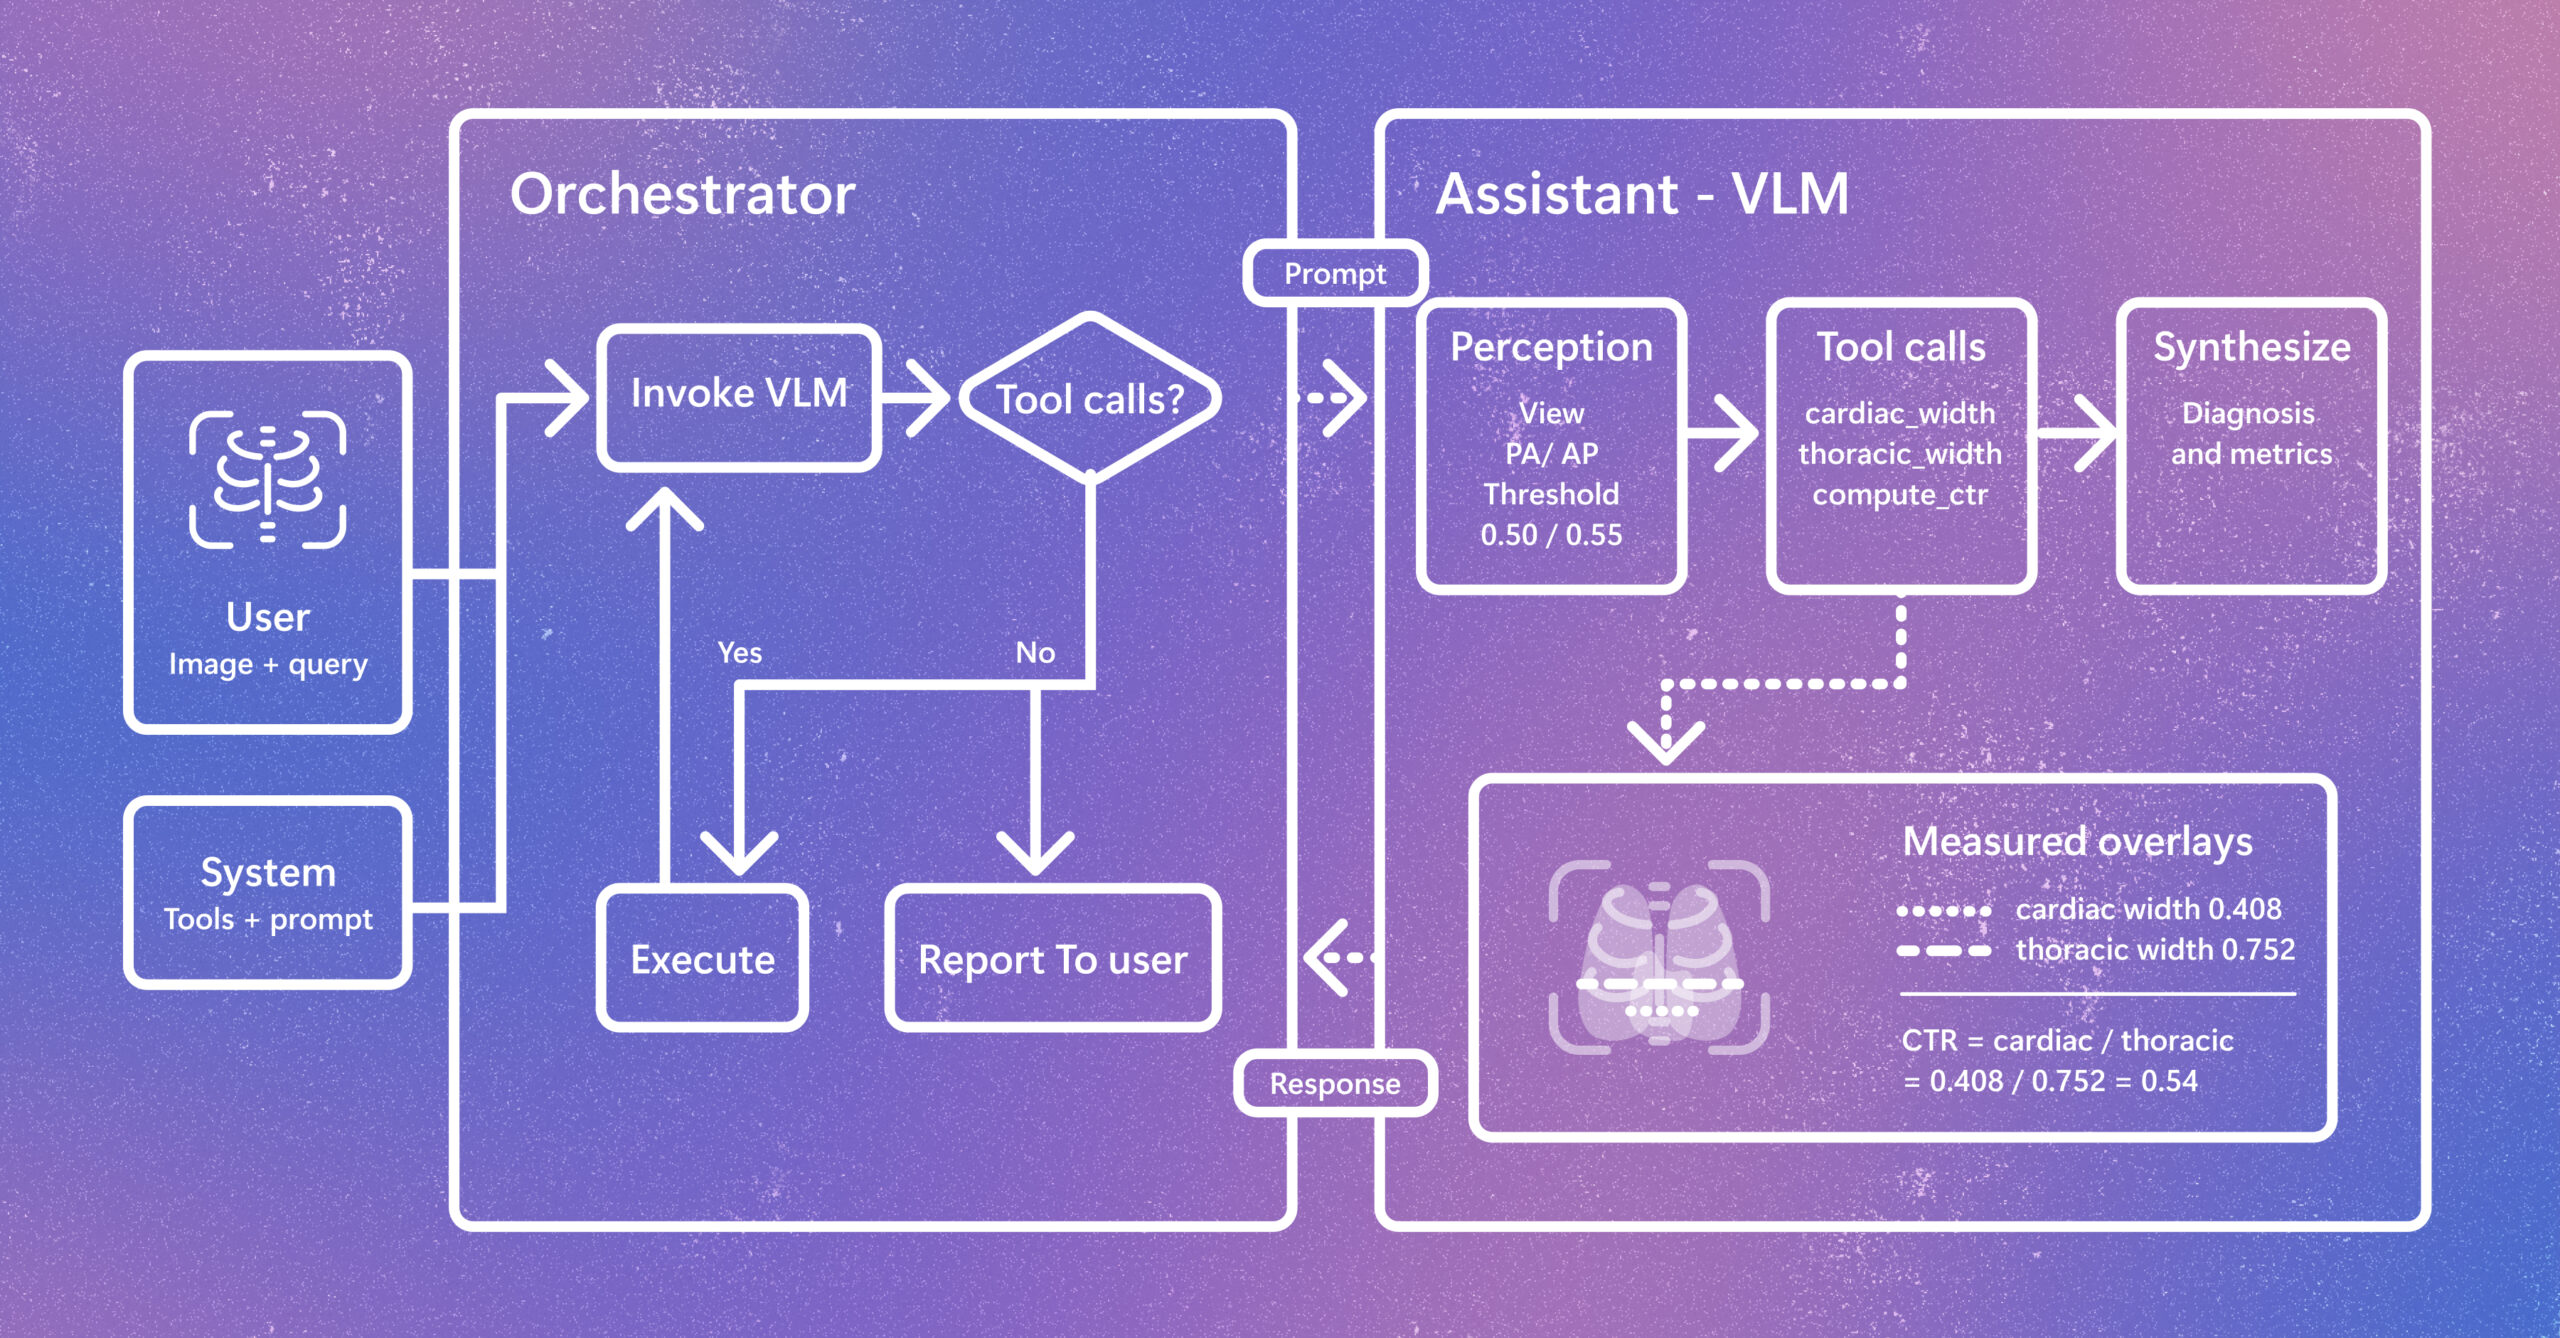
Radiology AI is evolving beyond report generation. CARE-X explores a unified approach that combines flexible reasoning, calibrated predictions, and measurement-based tools for chest X-ray interpretation. The post Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement appeared first on Microsoft Research.