Skip to content

An Empirical Study of Harness Design for Coding Agents

Sep 2026 · 1 citation · ⚡ 1 influential · 37 references
Computer Science

TL;DR

This work studies a lightweight coding harness whose execution loop is fixed while three components are varied: planning, action space, and context management, and finds that context management becomes increasingly valuable as the context-window budget tightens.

Abstract

Coding harnesses shape how autonomous coding agents translate model capabilities into long-horizon software-engineering performance, yet existing work typically evaluates harnesses as monolithic systems, leaving the effectiveness of individual components unclear. To enable component-level comparisons, we study this question with a lightweight coding harness whose execution loop is fixed while three components are varied: planning, action space, and context management. Across four models evaluated on SWE-Bench Verified and Terminal-Bench 2.1, we evaluate 176 matched settings spanning five context-management strategies, four context-window budgets, and targeted ablations of planning and action space. We find that: (1) Context management becomes increasingly valuable as the context-window budget tightens, with most of its benefit coming from preventing context-overflow failures. (2) Staging rule-based elision before LLM-based summarization provides the strongest overall efficiency among the context-management strategies, whereas making elided content recoverable adds machinery that models rarely use and yields no accuracy gain. (3) Planning shifts from an accuracy scaffold for weaker models to a cost saver for stronger models, with little change in accuracy. (4) Predefined tools improve performance for models with weaker bash proficiency, whereas bash-capable models can operate effectively with a bash-only interface and achieve substantially lower cost, especially on command-line-centric tasks. Trajectory-level analysis explains these effects: context management extends execution trajectories without substantially altering agent behavior, planning changes where trajectories stop, and the action space changes the granularity at which code is written. These findings inform model- and budget-aware harness design and provide a modular framework for evaluating future harness components.
View source

Similar papers

Preprint Sep 2026

Beyond the Model: Demystifying Harness Effects in Software Engineering Agents

Large Language Model (LLM)-based agents are increasingly used for software engineering tasks, yet their performance is not determined by the base model alone. The agent harness substantially shapes how SE agents interact with repositories, execute actions, and validate solutions. However, the role of harness design rem...

Hai-Chuan Hu, Quan-Jun Zhang, Sheng-Cheng Yu et al. · 0 citations
Preprint Aug 2026

One Recipe, Many Harnesses: What Self-Evolution Encodes Across Languages and Models

Together, these results recast the evolved harness as a legible compensation layer, shaped jointly by the language's engineering demands and the model's behavioral gaps, rather than an opaque benchmark-tuned scaffold.

Siqi Yang, Qianlan Yang, Yu-Xiong Wang et al. · 2 citations
#artificial intelligence Preprint Sep 2026

Grow the Harness, Not the Context: From Strategy-Free Scaffolds to Reusable Specialist Agents

Large language model (LLM) agents often handle streams of related tasks, yet standard harnesses repeatedly ask the model to reconstruct the same control decisions inside each task's context. We study whether task feedback can instead turn recurring control into reusable executable code, while reserving LLM calls for ta...

Lai-Zhen Li, Jia-Rui Li, Juanjuan Zhao et al. · 1 citation
#natural language process... Preprint Sep 2026

HarnessDev: Can LLMs Create and Evolve Their Own Agent Harness?

It is found that generated harnesses remain substantially behind mature human-engineered references on code and on search and research, while matching or exceeding the selected references on writing and machine-learning experimentation, with large variation in execution cost.

Yu-Hao Wu, Jing-Yuan Zhang, Jia-Jun Shi et al. · 5 citations
Review Open access Sep 2026

LLM-Based Autonomous Agents: A Systematic Review and Critical Synthesis of Architectural Paradigms, Memory Models, Planning Strategies, And Operational Limitations

Large Language Models (LLMs) have enabled the emergence of autonomous AI agents capable of reasoning, planning, tool use, and iterative decision-making. Despite rapid development, the field remains architecturally fragmented, with limited conceptual clarity regarding memory integration, planning mechanisms, and oper...

Chukwuemeka Christiantus Ndubuisi · 0 citations
#artificial intelligence Preprint Sep 2026

Harness-of-Harness: Multi-Day Autonomous Software Development with Continual Improvement

In a multi-day deployment with more than 70 iterations, HoH autonomously develops a first-person-shooter game, featuring a coherent storyline, fully implemented core mechanics, human-playable experience, polished visuals and integrated audio.

Hao Yan, Min-Le Su, Hang-Fan Zhang et al. · 2 citations

Related blog posts

MIT News · Artificial Intelligence Sep 29, 2026

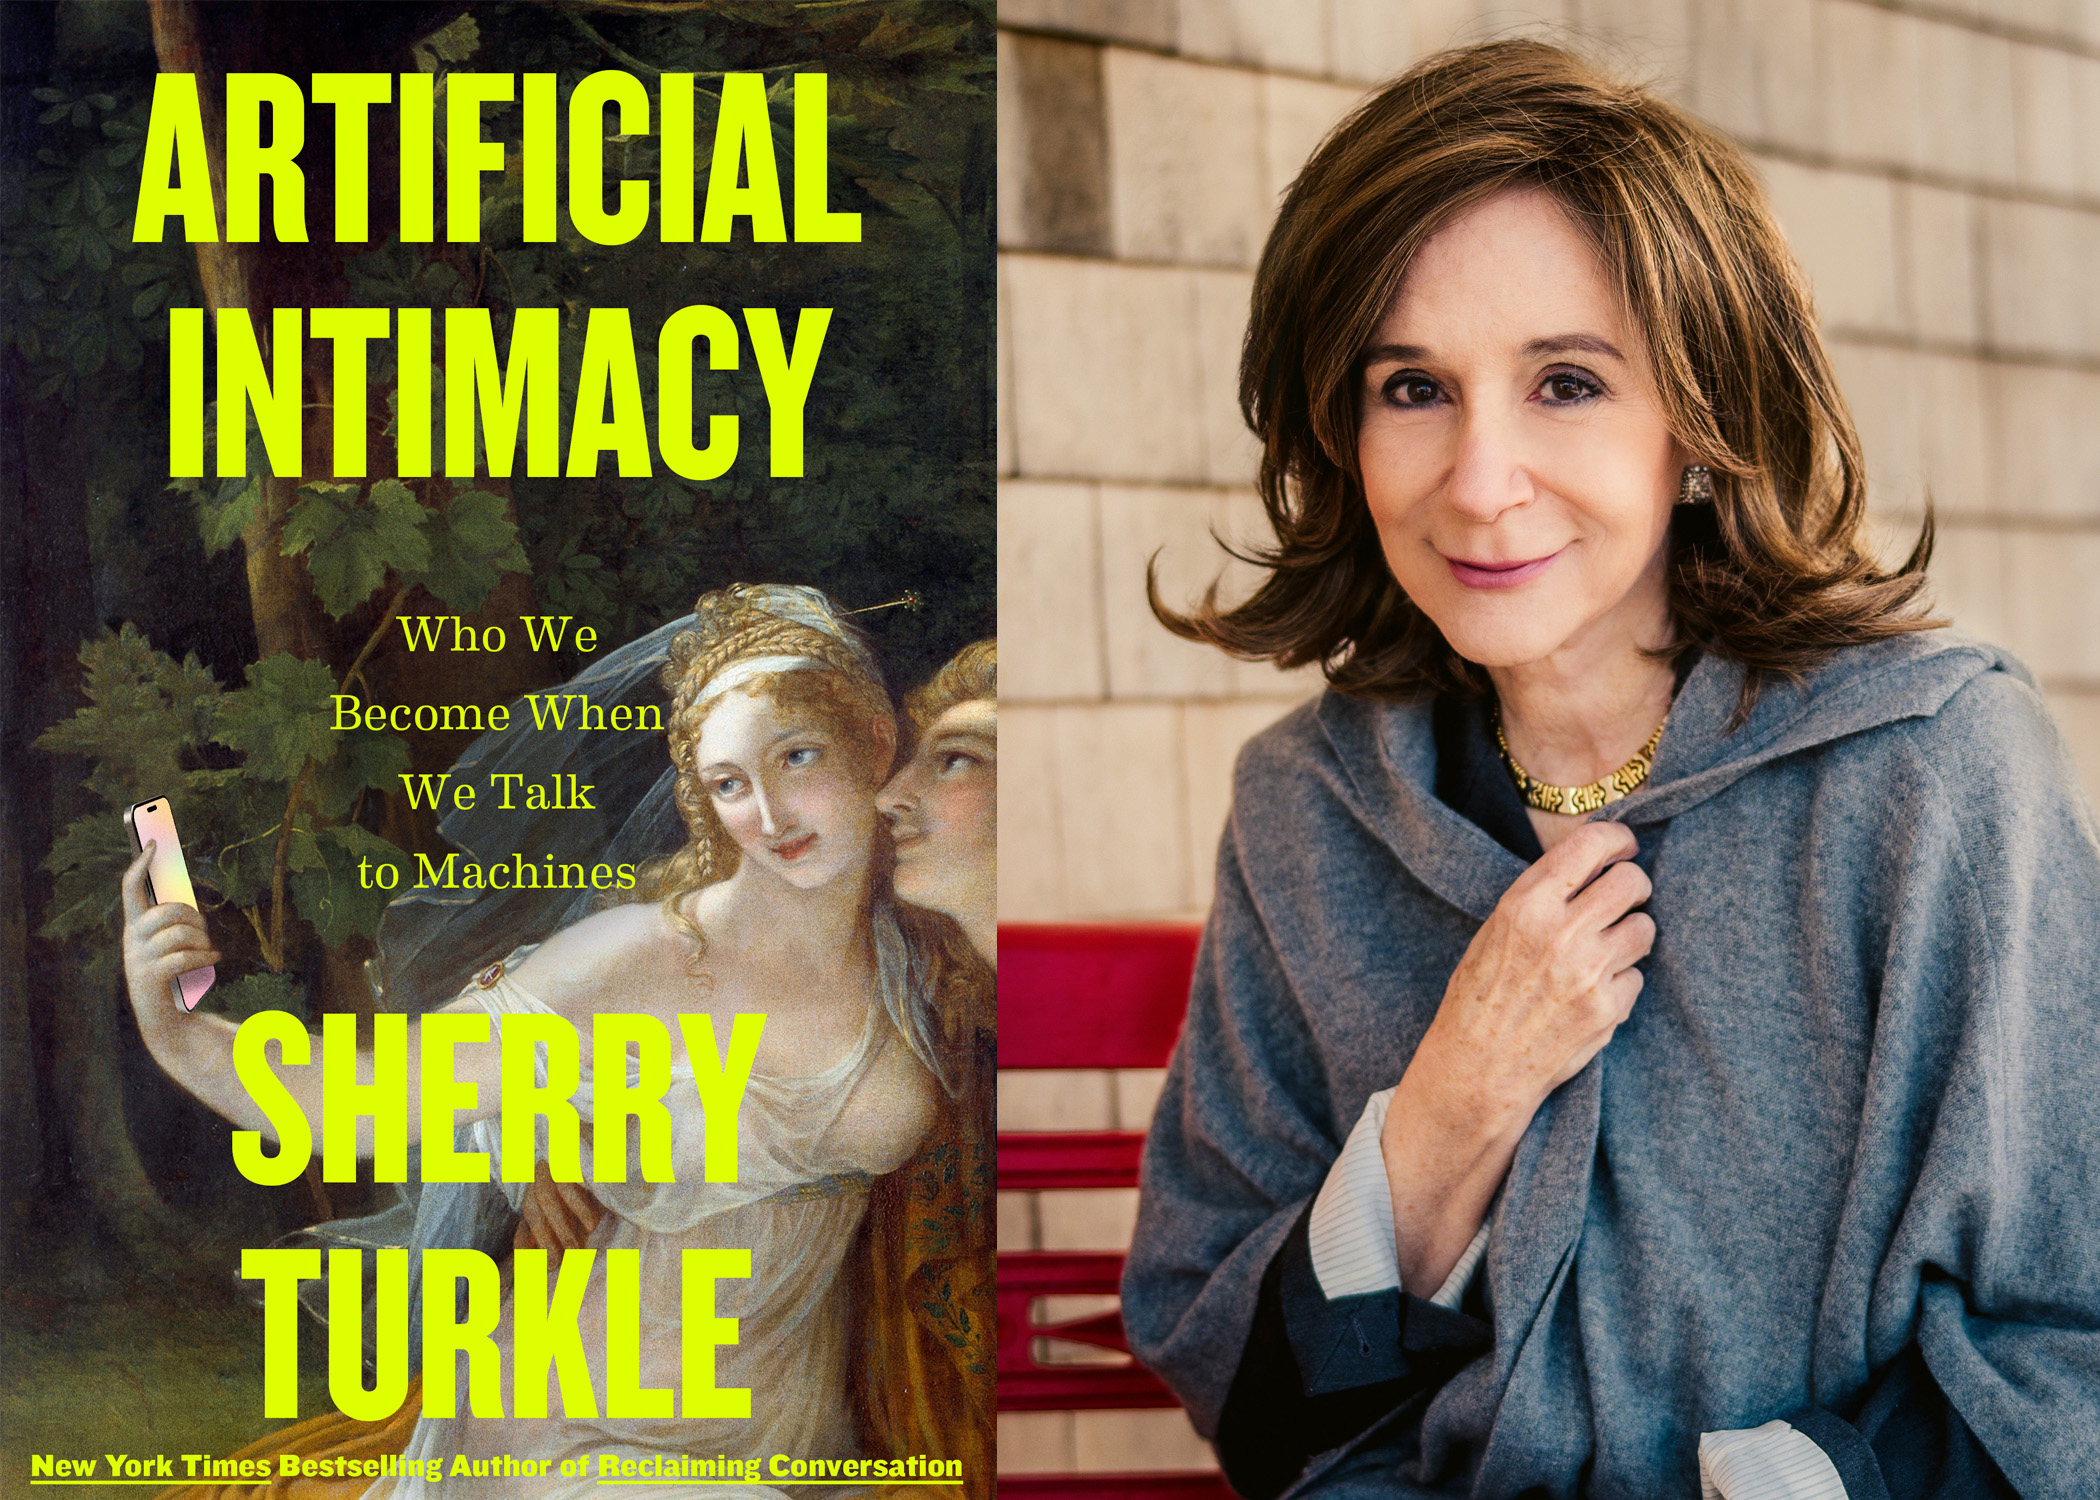
Who we become when we talk to machines

Professor Sherry Turkle’s new book, “Artificial Intimacy,” offers a withering critique of chatbots and the antisocial dynamics she believes they encourage.

MIT News · Artificial Intelligence Aug 27, 2026

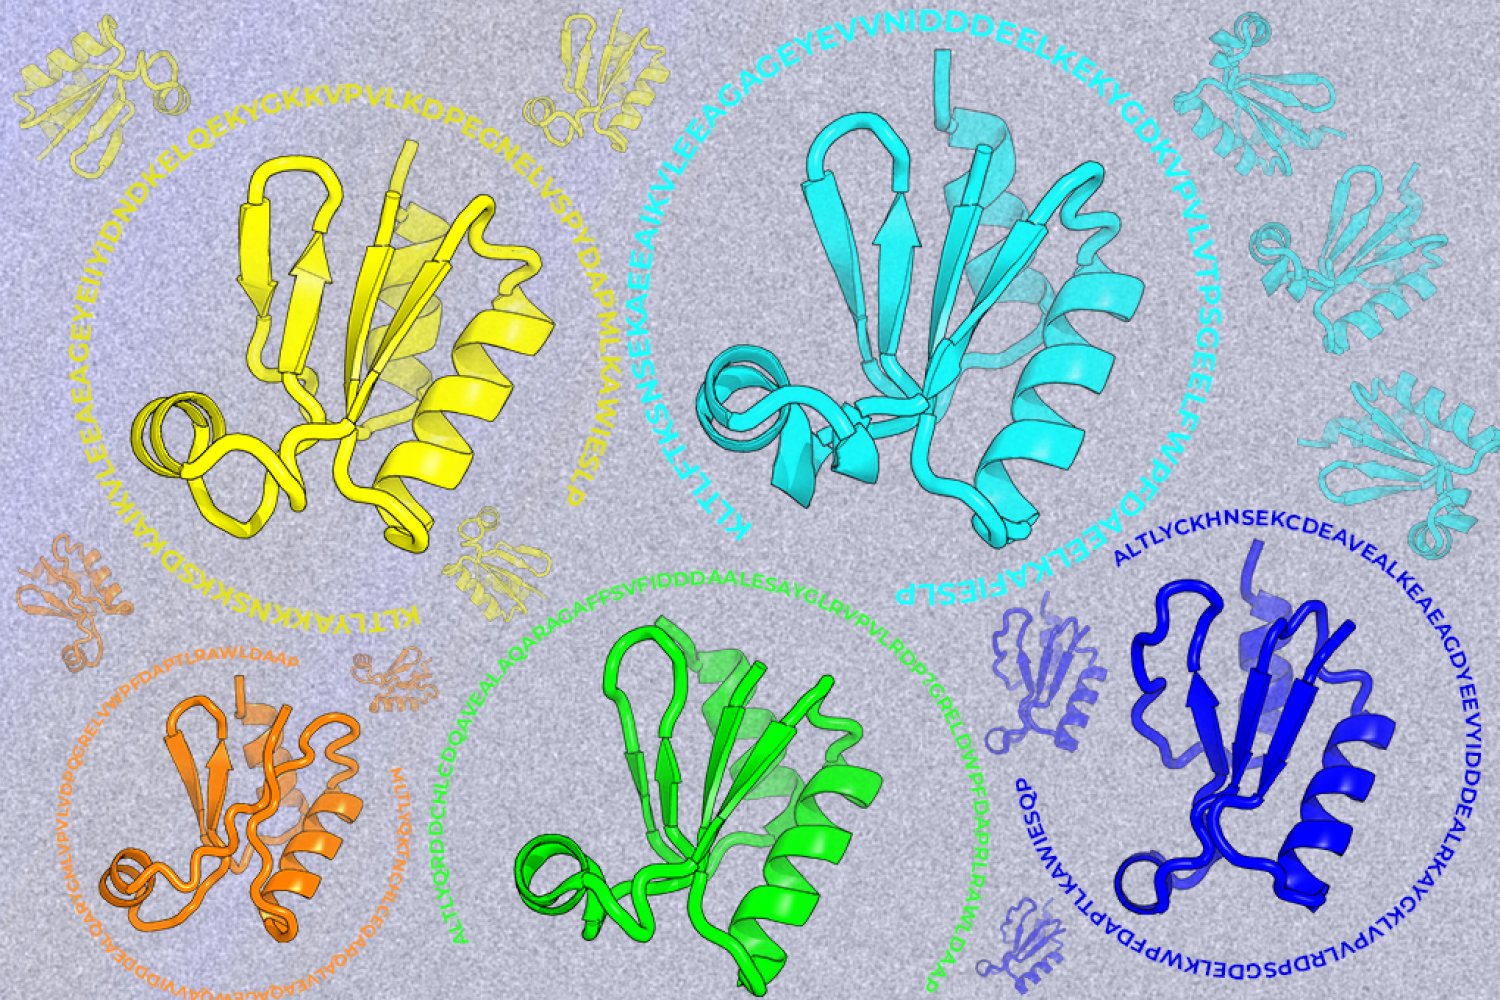
Looking beyond natural sequences

A new machine-learning framework aims to improve the success rate of computational protein design while moving away from results that reproduce sequences found in nature.

We use cookies to run the site and, with your consent, for analytics and to show ads. See our Cookie Policy.