Across seven Southeast Asian languages, broad capability gains are observed with the 120B-A12B model showing broader and more consistent improvements across tasks, with the 30B-A3B model showing broader and more consistent improvements across tasks.
Abstract
We introduce Nemotron-SEA-LION-v4.8, a family of Southeast Asian Languages In One Network (SEA-LION) models built upon NVIDIA Nemotron 3. The family includes 30B-A3B and 120B-A12B models, with both continued-pretrained base checkpoints and post-trained variants. We adapt the models using Southeast Asian, reasoning, code, and multilingual parallel data, followed by post-training with supervised fine-tuning and online on-policy distillation. On SEA-HELM, the 30B-A3B model improves the overall SEA score from 46.06 to 51.57, while the 120B-A12B model improves from 49.30 to 63.44. Across seven Southeast Asian languages, we observe broad capability gains with the 120B-A12B model showing broader and more consistent improvements across tasks.
To support long contexts efficiently, Sparse Gated Attention (SGA), which combines sparse attention with gated attention, and adopt Gated Norm (GN) to stabilize large-scale training is introduced, which keeps 4-bit NVFP4 serving within one point of FP8 accuracy.
Cheolseung Baek, Dhammiko Arya, Eunki Kim et al.· 0 citations
Manac-a-1B is the strongest model below the 7B scale, exceeding both Tucano-1b1 and Tucano-2b4 on LAMBADA-PT with large paired margins and is competitive on commonsense completion and near chance on multiple-choice reasoning, as are all small base models.
Bruno Leonardo Santos Menezes, Carlos Leonardo Souza Cardoso, Fábio Porto· 0 citations
This paper describes our system for Task~2 of the second Multilingual Conversational Speech Language Model (MLC-SLM) Challenge. We adapt Qwen3-Omni-30B-A3B-Instruct with a segment-evidence-aware data and post-training pipeline. A language model converts timestamped ASR into coherent event spans, which are expanded by a...
Instella-MoE is introduced, a fully open Mixture-of-Experts (MoE) language model with 16 billion total parameters and 2.8 billion active parameters per token trained entirely from scratch on AMD Instinct MI300X and MI325X GPUs, establishing a strong, fully open foundation for efficient, high-performing MoE models and r...
Jiang Liu, Sudhanshu Ranjan, Prakamya Mishra et al.· 0 citations
Cantonese is widely spoken but remains low-resource in written data, with no large corpus of native Cantonese reasoning traces available for model training. We develop and release CantoneseLLM v2, comprising models based on Qwen3 8B and 30B-A3B. The models are trained through CPT on 784 million Cantonese and Hong Kong-...
Tsz-Chung Cheng, Chung-Shing Cheng, Chaak-ming Lau et al.· 0 citations
We describe ufakzeka-1, a 151M-parameter (182M with embeddings) decoder-only Turkish language model pretrained from scratch on 13.5B tokens of openly licensed text and instruction-tuned for chat, at a total cost of about \$286 in cloud GPU, API and notebook time. The contribution is not the model's capability, which is...
Sait Furkan Teke· 0 citations
Related blog posts
MIT News · Artificial Intelligence· news.mit.eduSep 24, 2026
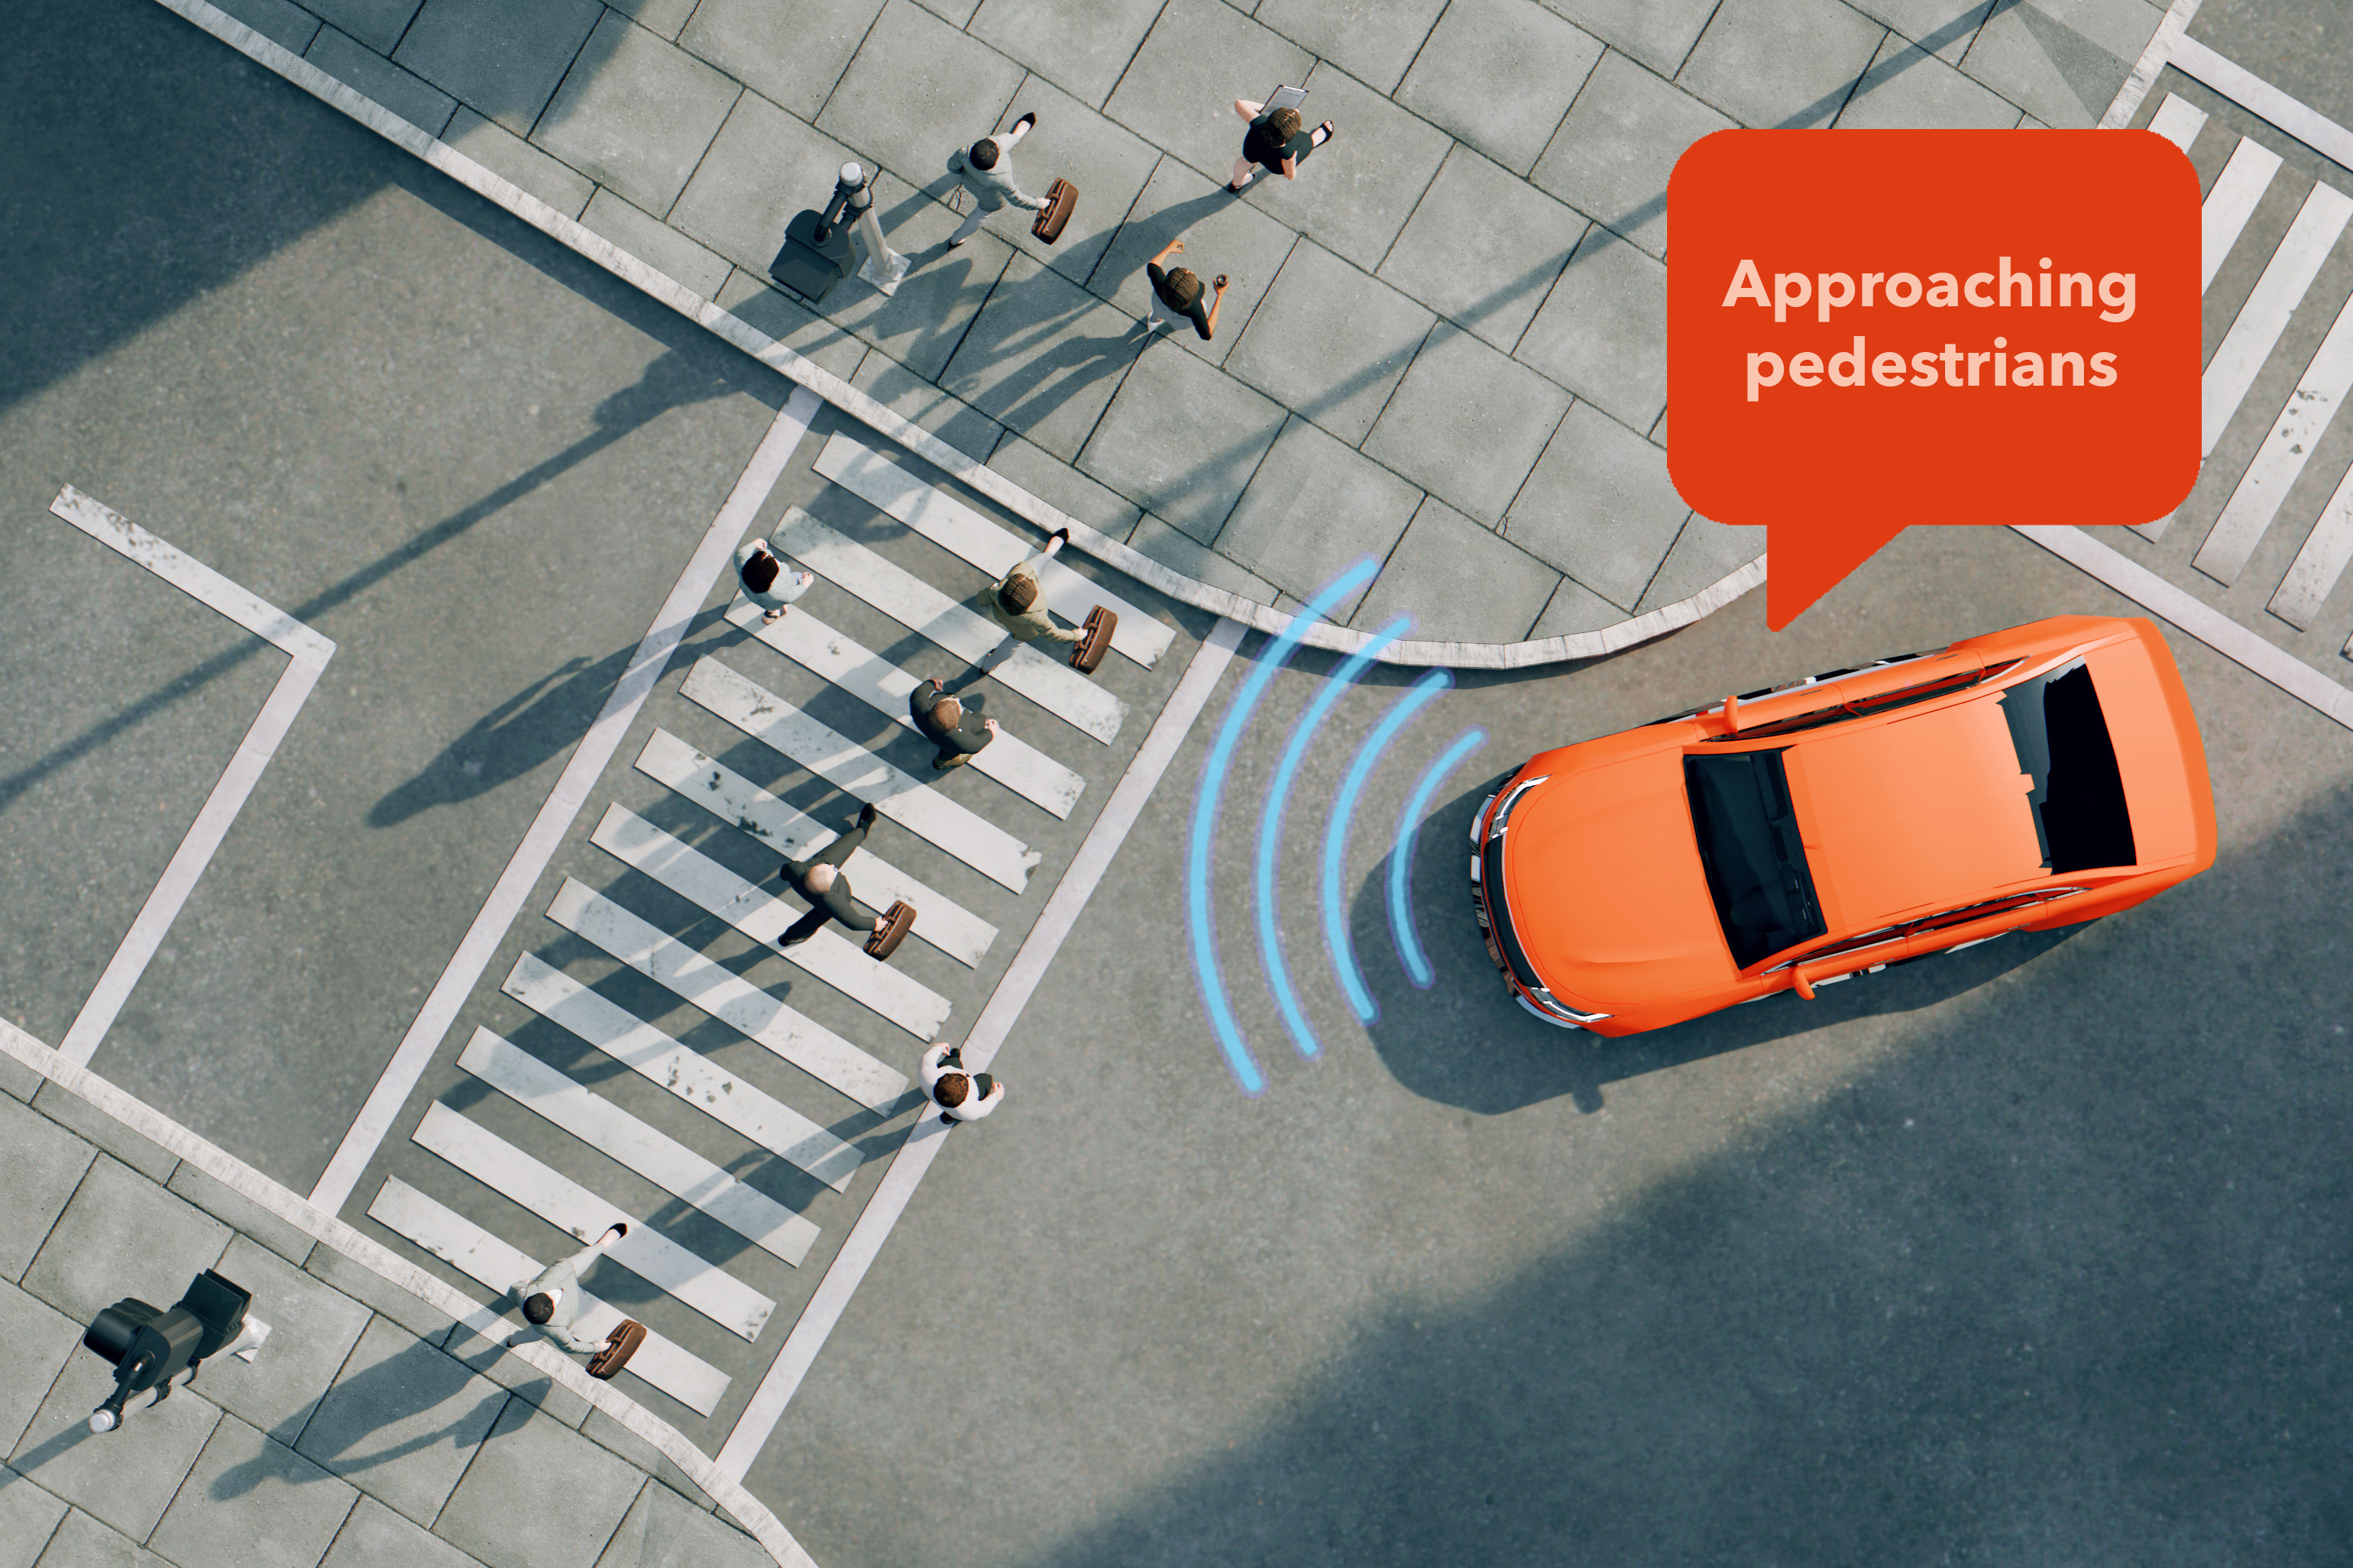
A new method, called CW-Net, translates the reasoning process of an autonomous vehicle’s AI system into understandable concepts that explain its behavior.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.